This page shows the project's results. The methodology, the design decisions and the limitations are documented in the repository's README.
7. Validated results
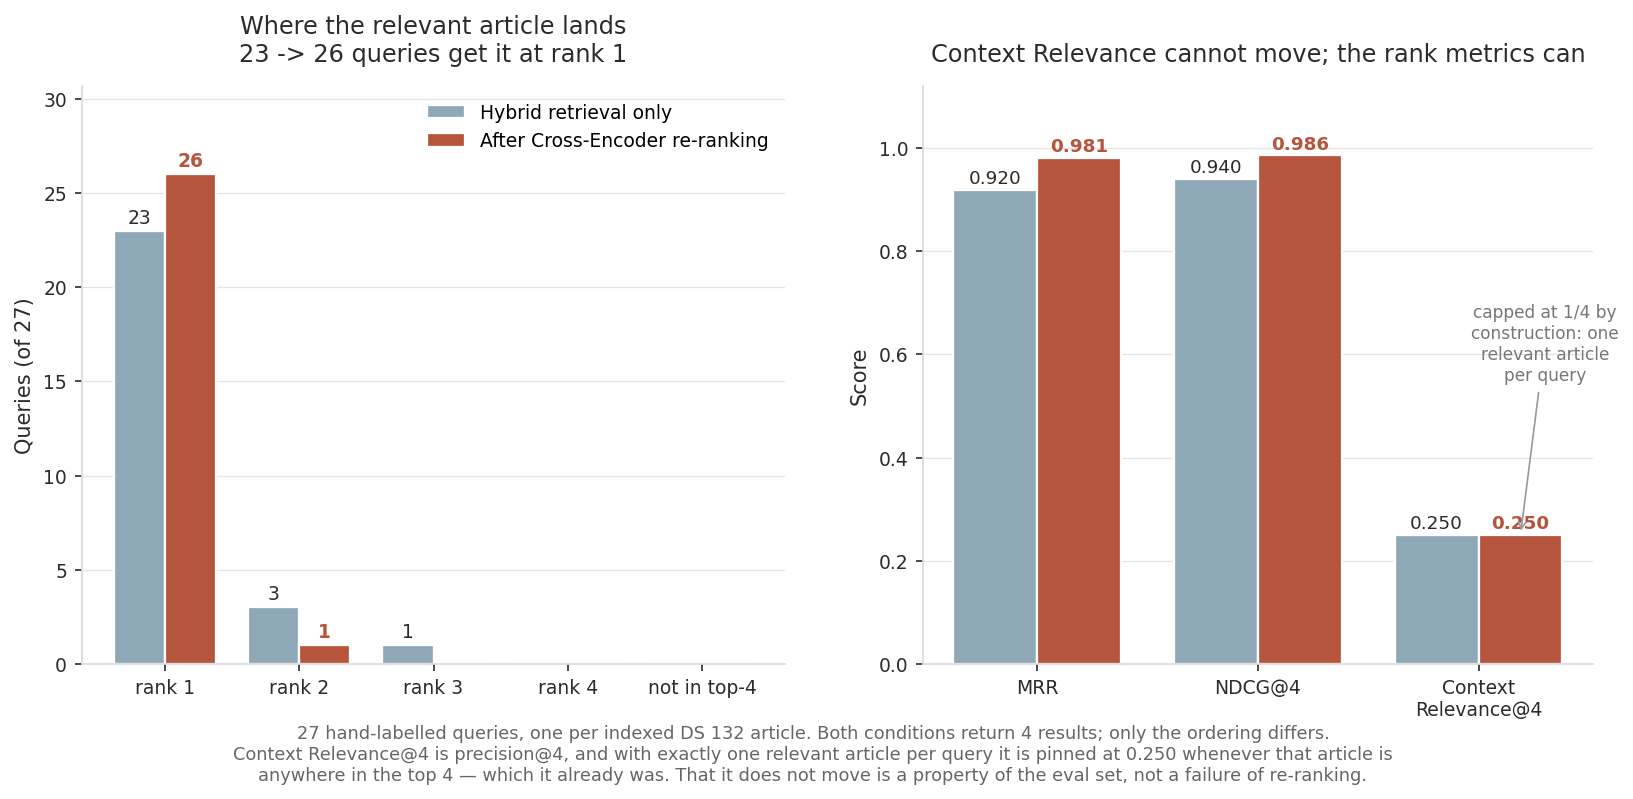
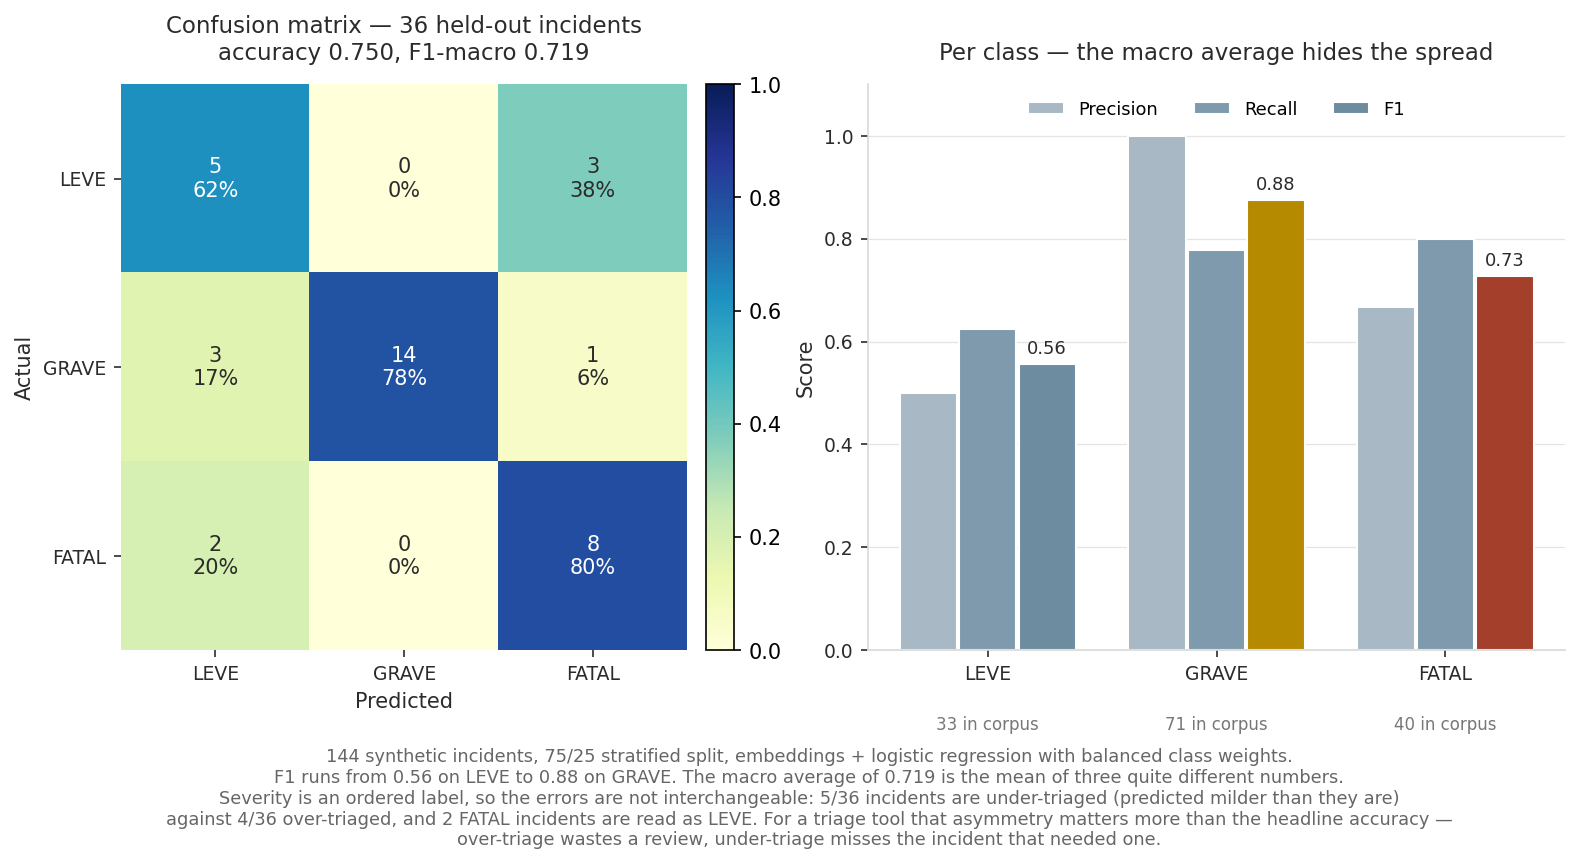
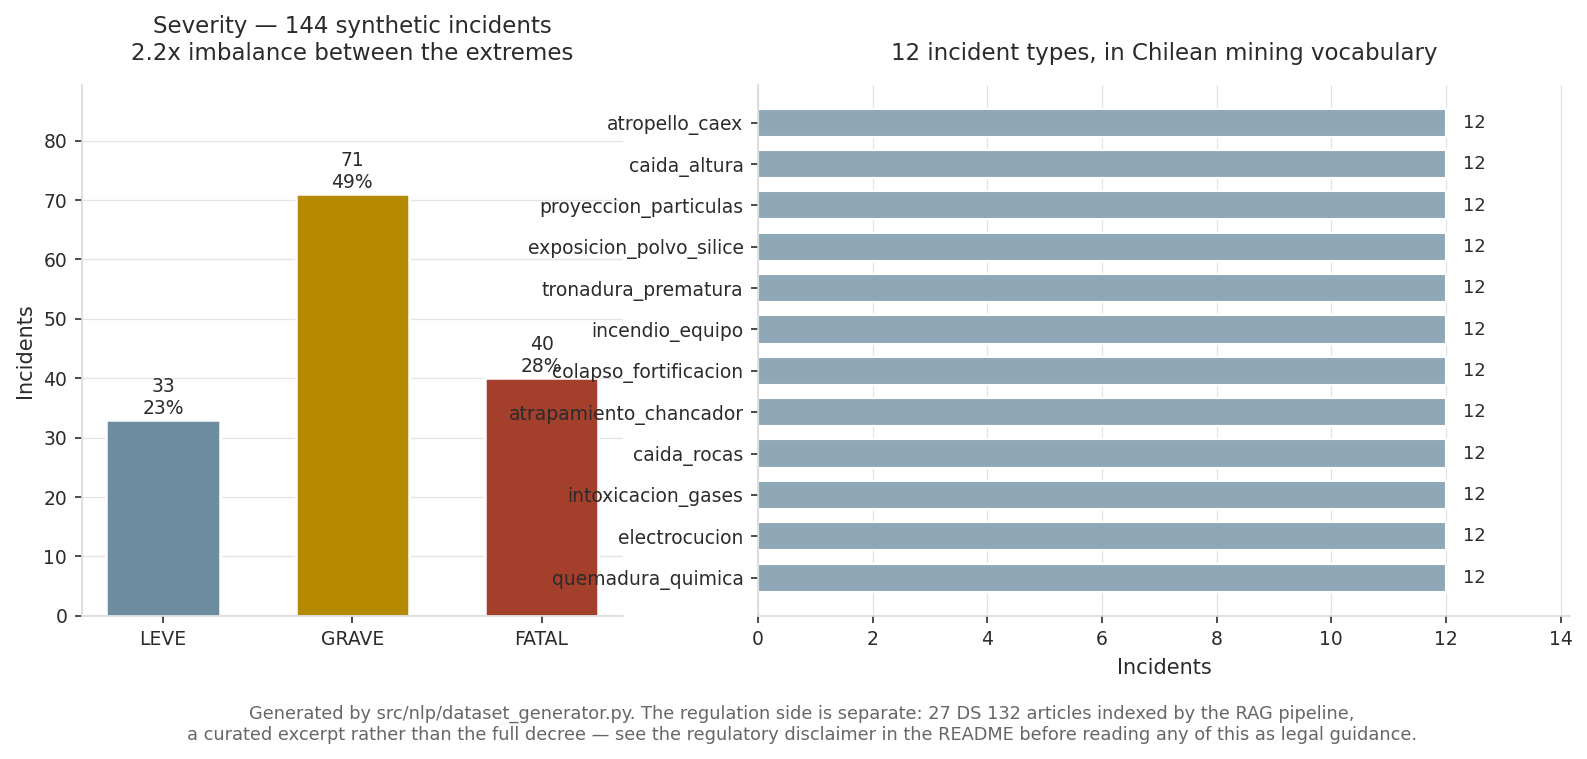
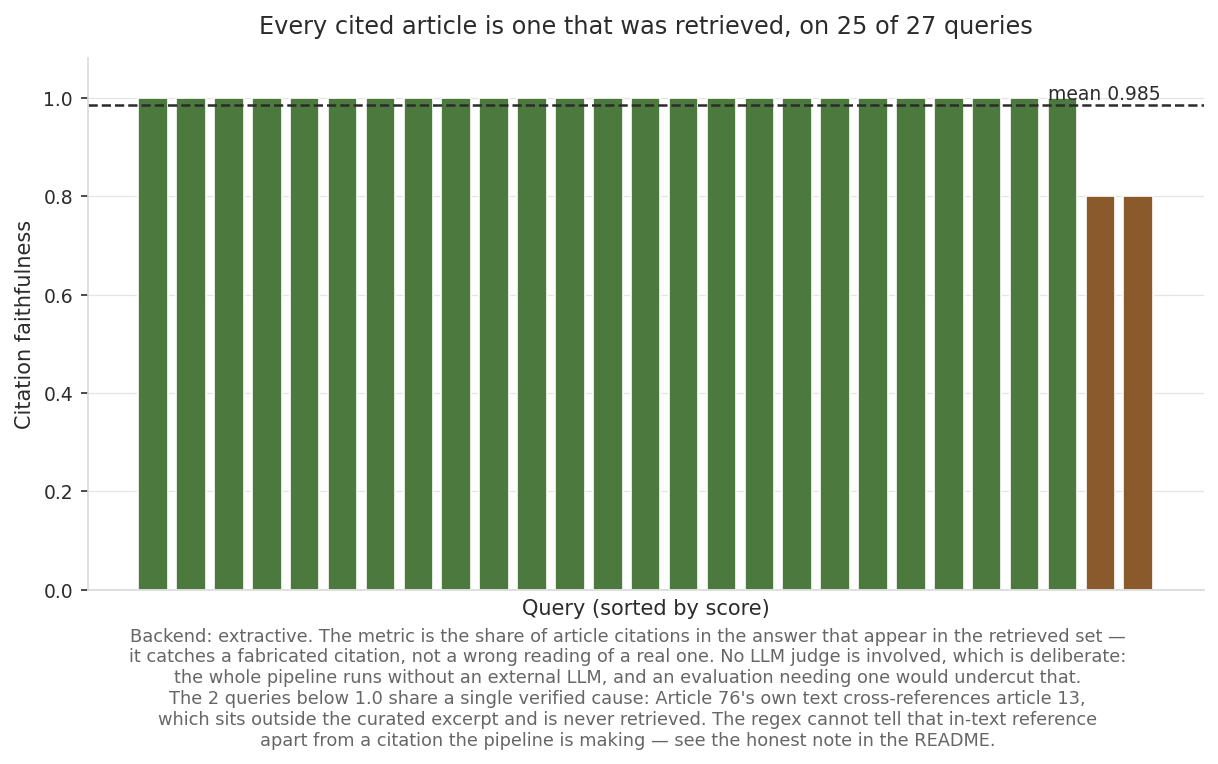
Honest note on Context Relevance@4 staying flat: almost every query in the evaluation set has exactly one truly relevant article, and that article was already inside the hybrid retriever's top-4 *before* re-ranking — so precision@4 is capped at 1/4 = 0.250 in both conditions by construction of the dataset, not because re-ranking did nothing. What re-ranking changed is *where* that relevant article lands within the top-4, which is exactly what MRR and NDCG measure, and both improved.Honest note on the classifier: the headline accuracy hides two things worth stating.The severity imbalance in the generated corpus (GRAVE 71, FATAL 40, LEVE 33 — a 2.2x spread between the extremes) is the most likely reason LEVE is the weakest class, even with class_weight="balanced" in the logistic regression.Citation faithfulness is 1.0 on 25 of 27 queries. The metric is purpose-built and narrow on purpose: it checks that every article the answer cites is one that was actually retrieved, which catches a *fabricated* citation but not a wrong reading of a real one. It needs no LLM judge, which is deliberate — the whole pipeline runs without an external LLM, and an evaluation that required one would undercut that.